
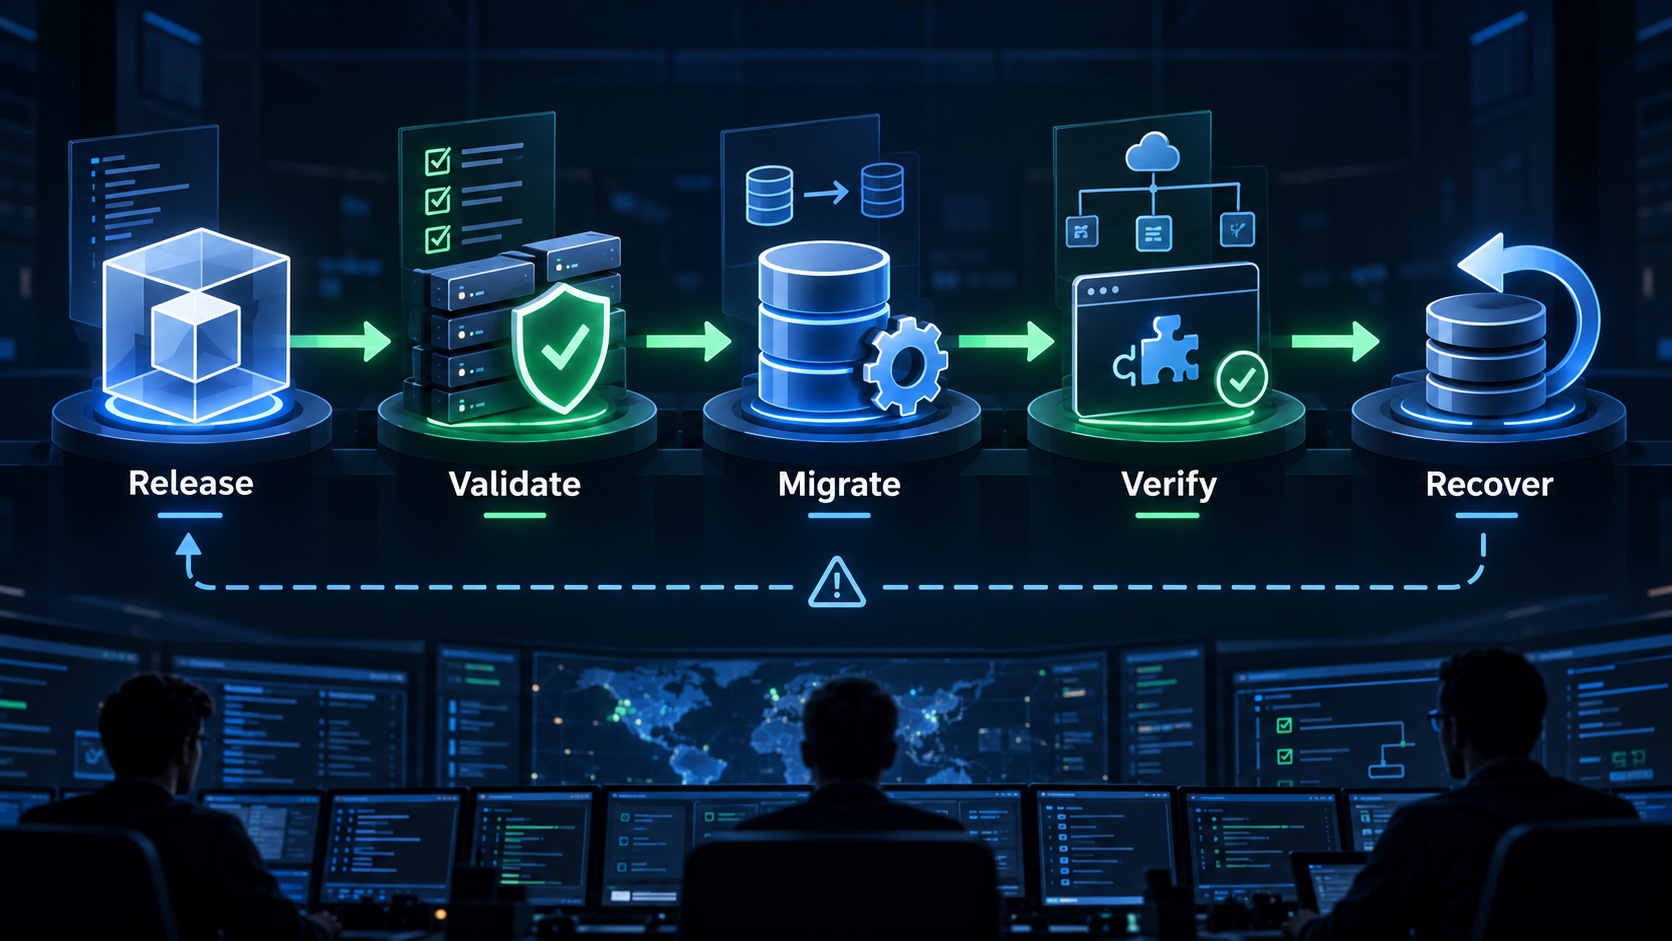
A SaaS deployment is complete when the intended release can perform its critical customer workflows in the target environment and the team can detect and recover from failures. A green build and a responding homepage are necessary checks, but they do not establish that billing, invitations, storage, or background work are functioning.
Use a checklist organized around evidence. Each item should identify what must be true and how you will verify it. This makes the process usable by a small team without turning deployment into a collection of unchecked assumptions.
Identify the exact release
Record the source revision, dependency state, build artifact, and configuration changes associated with the release. The deployed web process and workers should be traceable to known versions. This is essential when an incident appears only after a particular change.
Confirm that the build uses the intended runtime and production settings. Review warnings that affect supported behavior rather than treating every warning as equally urgent. A reproducible artifact helps you distinguish a code problem from a difference between the environment that built it and the environment running it.
The Next.js production checklist is a useful framework-specific companion covering performance, security, and production preparation. Apply that guidance to the actual application and deployment arrangement, including any background services outside the web process.
Validate the target environment
Verify the public domain, allowed authentication callbacks, database connection, storage destination, email sender, billing environment, and webhook secrets. Values should correspond to one intended environment. A staging deployment with one production credential is an environment mismatch even if most services are safely isolated.
Check build-time settings separately from runtime settings. Confirm that the visible site URL and browser configuration are correct after deployment. The fact that a secret manager contains a new value does not prove every running process has loaded it.
Review access to deployment controls. The people who can change production configuration, issue provider credentials, and restore data should be known. Keep the ability to perform recovery available without sharing a universal administrative account through the team.
Prepare database and storage changes
Identify pending migrations and the order in which they must run relative to new application code. Check compatibility with old processes that may still handle requests or finish jobs. Destructive cleanup should have an explicit justification and a recovery decision.
Verify backup and restoration procedures before a change that could affect customer data. Confirm that backups include the required database scope and that uploaded files have their own protection where necessary. A relational backup does not automatically include objects stored elsewhere.
For a migration involving historical data, define the expected counts and relationships after processing. Record where backfill progress can be observed. A release should not be declared complete while required records remain in an unknown intermediate state.
Check integrations from the deployed application
Authentication needs to complete the full redirect or email-link journey on the real deployed origin. Invitations should point to the right environment, expire as intended, and create the correct membership. Email should use the configured sender and a controlled test recipient during verification.
Billing verification should cover the application's interpretation of provider events. Confirm that a purchase or subscription update leads to the expected entitlement in the correct workspace. A successful checkout page says little about whether a webhook was accepted and processed.
For uploads, verify creation, authorized retrieval, and denial from an unrelated workspace. Check download links generated by background jobs as well as those created directly by the web application. Different code paths can accidentally use different storage or authorization settings.
Include workers and scheduled work
List the job runners, schedules, and event consumers required by the release. Confirm they are running the intended code and can access the services they need. A web deployment can look healthy while reminders or reconciliation jobs remain on an obsolete version.
Check that retries do not duplicate business effects. Know how to find a failed job and decide whether it is safe to replay. Keep a clear distinction between pending work, work currently executing, work eligible for retry, and work requiring manual intervention.
If a release changes a job payload, account for jobs already queued. The worker must either understand the older shape or have a controlled migration or draining strategy. Discarding pending customer work should never be an accidental consequence of a schema change.
Rehearse one complete customer journey
Consider a hypothetical field inspection SaaS. The release changes report exports. Its deployment verification should create a controlled workspace, record an inspection, generate a report, retrieve the file as an authorized member, and confirm another workspace cannot retrieve it.
Now add a temporary provider failure in staging. Verify that the report remains recoverable, the UI shows an understandable state, and the operator can identify the failed step. This focused rehearsal tests the changed behavior more effectively than opening every navigation item.
Keep production checks bounded and clearly identifiable. Avoid generating uncontrolled customer notifications or polluting real analytics. Remove disposable records through a documented cleanup path after retaining the evidence needed for the release record.
Define when to stop or recover
Write explicit stop conditions before deployment. A broken sign-in flow, cross-workspace access, or incorrect paid entitlement requires a different response from a minor visual defect. Give the person running the deployment authority to halt further rollout when those conditions appear.
Record which recovery action is appropriate: redeploy the previous application, disable a changed capability, apply a forward repair, or restore data under an agreed recovery process. Reverting code cannot automatically reverse every database or provider-side effect.
After release, watch the customer outcomes most likely to reveal trouble and record unresolved issues with owners. Agentium Start marks deployment guides as partial in its capability scope. Use the published scope as an input, then maintain a deployment checklist verified against your own infrastructure and paid workflows.
Authority References & Sources: