LLM-as-a-Judge vs Human Review: How to Evaluate AI Responses
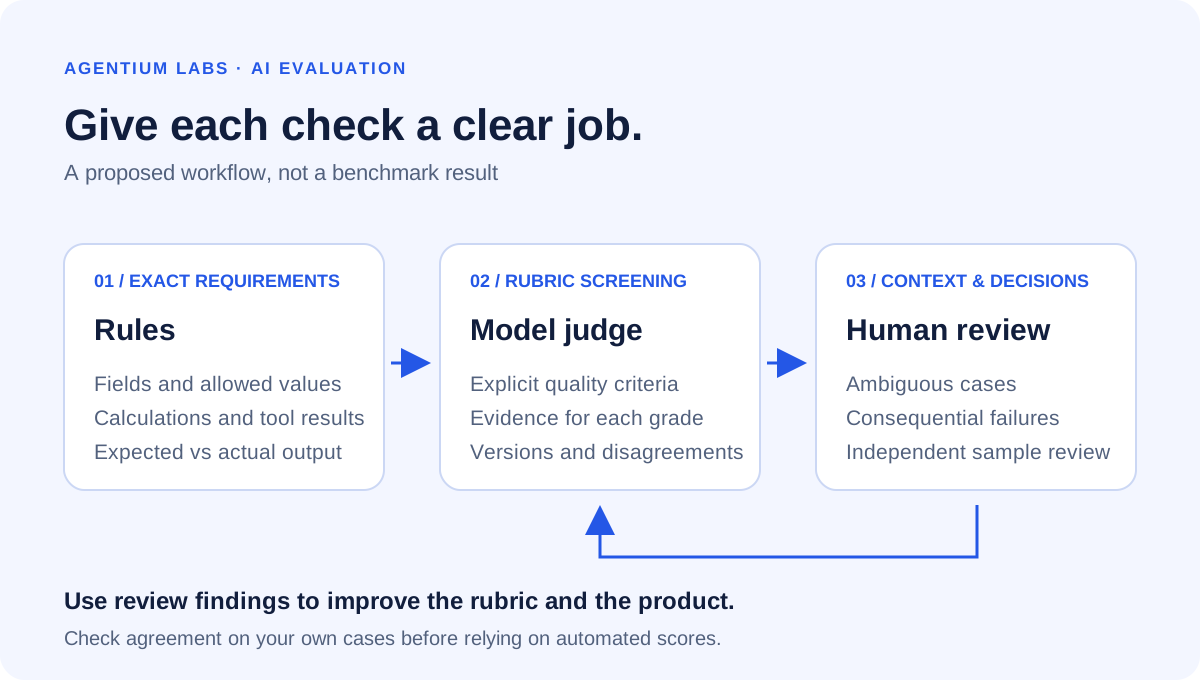
Compare model judges, human reviewers, and rule-based checks. Build an AI response evaluation workflow with clear criteria, evidence, and review ownership.
Agentium Journal · AI quality
Evaluate model responses, inspect completed conversations, and understand what a quality score can prove.
Inspect an evaluation score →Compare model judges, human reviewers, and rule-based checks. Build an AI response evaluation workflow with clear criteria, evidence, and review ownership.
Turn completed voice-agent conversations into reviewable cases: define inputs, separate transcript evidence from audio, and build a practical scorecard.